
Midjourney用新的图像到文本生成器翻转公式

…
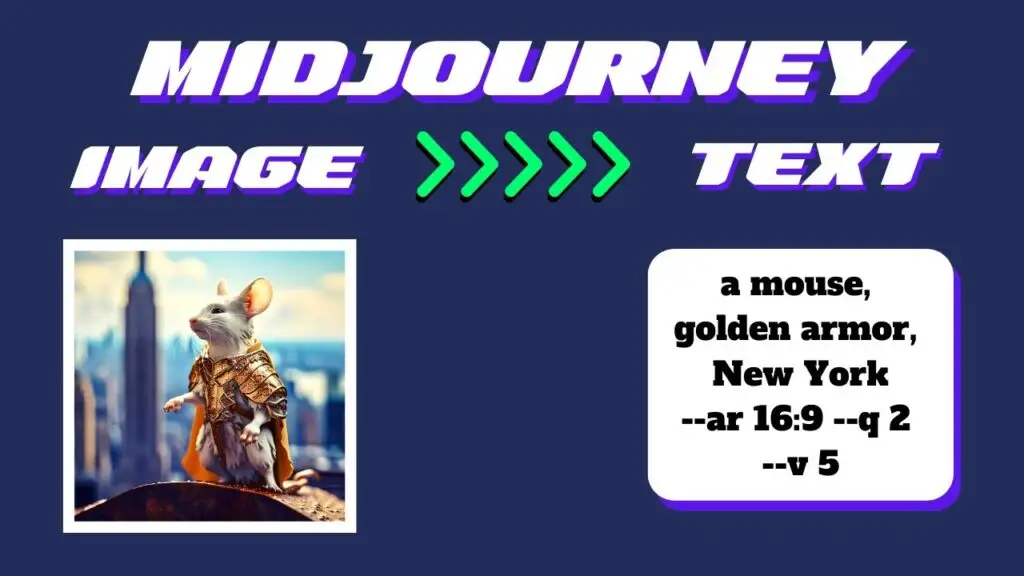
Midjourney宣布了一个新的”/describe”命令,允许用户利用强大的人工智能(AI)平台将图像转化为文字,颠覆了Midjourney将文本转换为图像的典型程序。
Paul DelSignore在Medium上描述了这一功能,他写道:”describe” 对广泛的使用案例有许多重大好处。
Today we’re releasing a /describe command that lets you transform images-into-words. Give it a shot! We think this tool will transform your liguistic-visual process both in terms of creative power and discovery.
今天,我们发布了一个 /describe 命令,可让您将图像转换为文字。试一试!我们认为该工具将在创造力和发现方面改变您的语言视觉过程。-Midjourney
描述功能的一个最好的方面是,它应该提高无障碍性。对于有视觉障碍的人来说,浏览网页可能是一种挑战。通过描述图片的Alt文本元素,使其更容易被访问。手动创建这些Alt元素是很耗时的,而Midjourney的描述功能可能会克服这一障碍。
改进的搜索功能几乎对每个互联网用户都有好处。当图片包含更好、更丰富的描述时,搜索引擎可以更有效地索引图片。
DelSignore还强调了标题的重要性,因为详细的标题有助于解释图像,为观众提供更清晰的信息。
图像到文本的生成与Midjourney的文本到图像系统创造了一个有趣的反馈循环。虽然Midjourney的用户已经可以根据选择生成类似的图像,但图像到文本的工具可能使其更容易为文本到图像生成器开发替代的和可能更有成效的描述。
我要在AE上重新混合我用Element 3D创建的一张图像
Using the /describe function to see what it says on #midjourney v5 is really interesting for prompt generation so will now see what they make.
将重新混合我在 AE 上使用 Element 3D 创建的其中一张图片
使用 /describe 函数查看它在#midjourney v5 上的内容对于提示生成来说真的很有趣,所以现在将看看它们做了什么。
–GooRee
在目前的迭代中,就像它的文本到图像生成器一样,Midjourney将为上传的图像创建四个不同的文本描述。还可以根据选定的描述生成新的变化。要上传一张照片,用户在文本字段中写下”/describe”,然后出现一个拖放式的上传字段。
然后,用户可以从生成的描述中选择一个,并使用新的文本提示 “remix” 上传的图片。用户还可以编辑文本提示,为创作过程增加一个新的控制元素。
测试Midjourney的新/describe功能
PetaPixel测试了该功能,首先使用了主编Jaron Schneider拍摄的肖像。
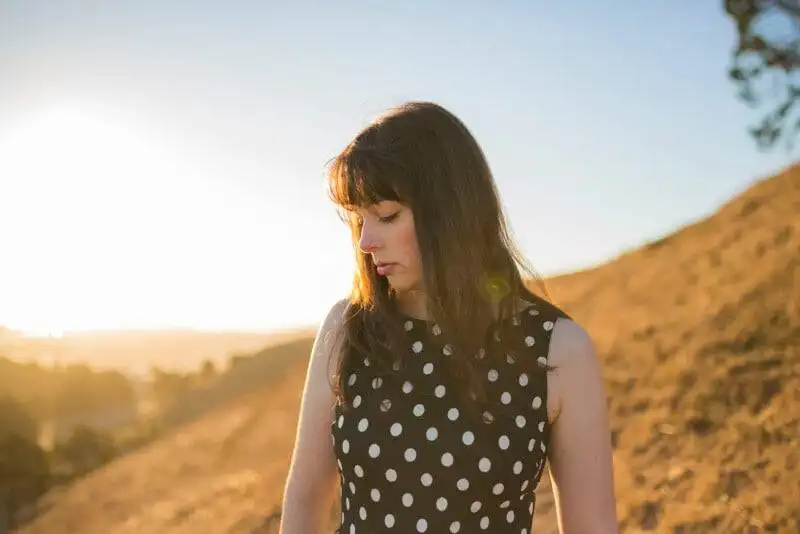
图片来源:Jaron Schneider
Midjourney的四个生成的描述质量不一。
- young woman in polka dot dress standing on top of hill, in the style of pensive portraiture, lens flares, voigtlander heliar 15mm f/4.5, troubadour style, close up, calarts, simple
- a young woman wearing a black and white polka dot dress standing, in the style of hazy landscapes, pensive portraiture, sun-soaked colors, candid portraiture, tumblewave, troubadour style, close up
- a young woman in black and white checkered dress standing on slope of hill, in the style of anamorphic lens flare, polka dots, california plein air, pensive stillness, sun-soaked colors, candid portraits, delicate
- leigh wyatt | san francisco weddings|daughtersmaidsoflake benson | san francisco, in the style of neo-pop sensibility, gentle lyricism
前两个描述相当不错,尤其是第二个描述。有趣的是,Midjourney描述了一个特定的Voigtlander 15mm prime镜头,尽管为了记录,该图像是用Tamron 35mm f/1.8 prime拍摄的。使用第二个描述来生成一个remix,导致了相当令人印象深刻的结果。
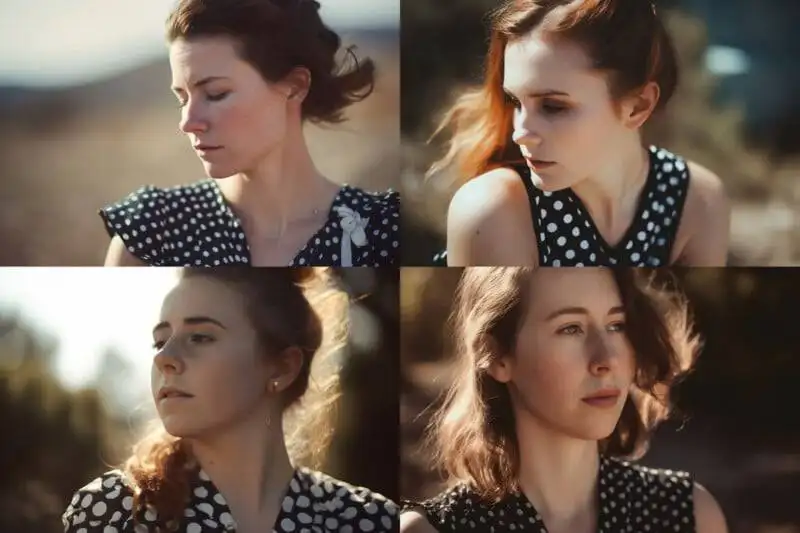
Midjourney v5使用 “a young woman wearing a black and white polka dot dress standing, in the style of hazy landscapes, pensive portraiture, sun-soaked colors, candid portraiture, tumblewave, troubadour style, close up“的原始肖像描述而生成的四张AI图片。
使用施耐德的另一张图片,这次是一张来自加利福尼亚莫诺湖的风景图片,Midjourney再次产生了大部分有用的文字描述,尽管有关于莫诺湖的错误位置信息。
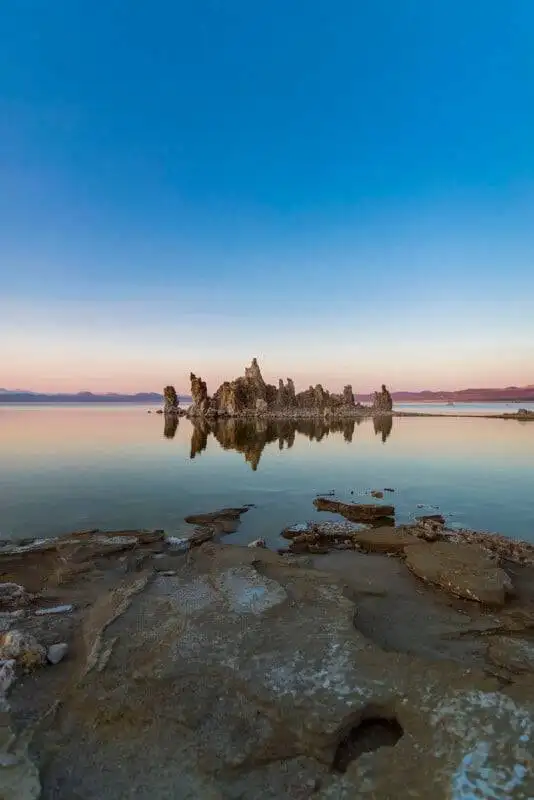
图片来源:Jaron Schneider
- monolake, las vegas, utah, united states of america near crystal, in the style of shot on 70mm, mikalojus konstantinas ciurlionis, post processing, 32k uhd, antoni gaud, hazy landscapes, fenghua zhong
- mono lake at sunset after a rain, in the style of focus stacking, light sky-blue and bronze, 32k uhd, national geographic photo, stock photo, dansaekhwa
- 犹他州mono lake,32 k超高清风格,平衡对称,美式调性,朦胧,梦幻般的品质,尼康d850,Fenghua Zhong
- 加州莫诺湖,日出照片1,32 k超高清风格,孤立景观,低景深
使用第三种描述作为remix提示,Midjourney提供了四个非常逼真的新图像。
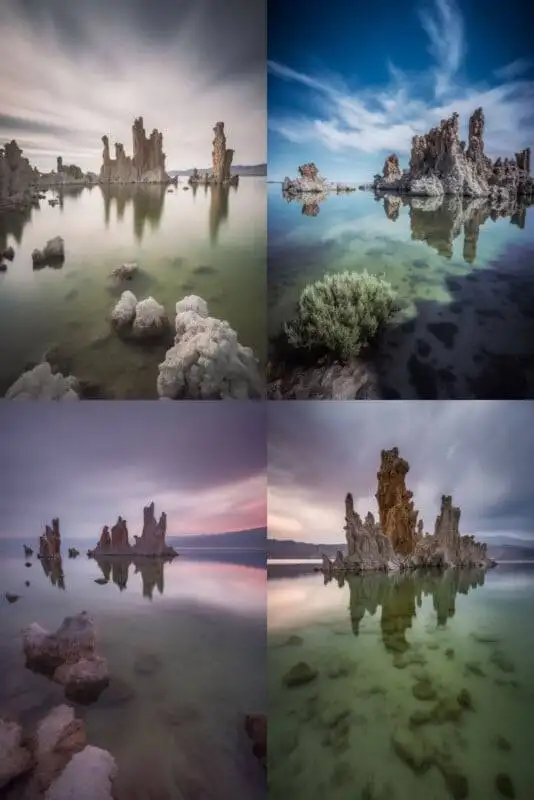
四张由人工智能生成的图像,基于 “犹他州mono lake,32 k超高清风格,平衡对称,美式调性,朦胧,梦幻般的品质,尼康d850,Fenghua Zhong”
Midjourney的/describe工具很吸引人,即使在其早期状态。这个工具应该可以帮助创作者制作更详细的Alt文本、标题,甚至不同的AI生成的艺术品。虽然描述的某些部分令人费解,但至少可以说,它们显示了前景。
声明:本站所有文章,如无特殊说明或标注,均为本站作者原创发布。任何个人或组织,在未征得本站同意时,禁止复制、盗用、采集、发布本站内容到任何网站、书籍等各类媒体平台。本文来自作者自媒体,不代表UIED观点和立场。 如若本站内容侵犯了原著者的合法权益,可联系我们进行处理以减少您的损失。
标签




评论 0
最新评论登录后发布评论并参与互动。
暂无评论,欢迎抢沙发。